Website basics
Distinguish robots.txt from noindex
robots.txt controls crawling, while noindex directs search indexing. Neither is a substitute for access control over private information.
On this page
Define the intended restriction
Decide whether a public page should be absent from search or whether viewing itself must be restricted. The latter requires an appropriate access-control mechanism.
Understand the crawling limit
Blocking crawling can still leave a URL known through links. Preventing retrieval is different from removing the URL from search.
Let the crawler read noindex
Google must access a page to see its noindex directive. Blocking the same page in robots.txt prevents that reading. An HTML directive can look like this:
<meta name="robots" content="noindex">Inspect production settings
Check both HTML and response headers for test-environment directives accidentally carried into production. Inspect the URL in Search Console and distinguish configuration verification from later search reprocessing.
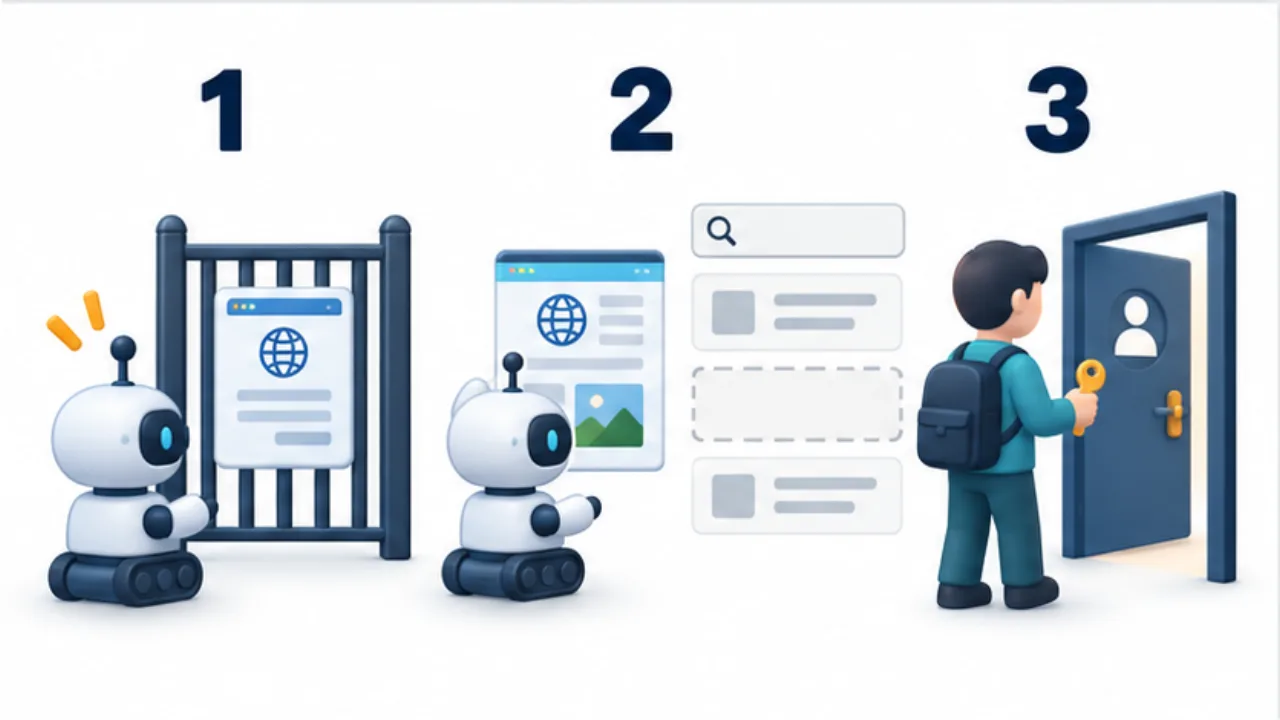
Select the image to enlarge.
- robots.txt directs crawler access.
- noindex asks a search engine not to index a page it can read.
- Private pages need access control such as authentication.
Classify the audience before choosing a mechanism
Keeping a public page out of search and limiting a page to named participants solve different problems. Ask whether someone who knows the URL may open it directly. That question separates search treatment from access control.
Do not label a search directive as completed privacy protection. A restricted document needs an appropriate access mechanism. A public article intended for discovery has the opposite review: test-environment restrictions should not remain.
Check whether a shared template is being applied to pages with different purposes.
Example: a test directive remains after launch
Suppose a site was excluded from search during development and is now public. Reviewing only the homepage does not inspect every article template.
Choose representative homepage, article, and category pages when they have different generation paths. Inspect their actual production HTML and response headers.
If an unwanted directive remains, correct the intended scope, regenerate, and verify the deployed response. Record the site-side correction separately from later search reprocessing. An absent search result immediately after the change is not, by itself, proof that the new configuration is still wrong.
Map the review to the purpose
| Purpose | What to inspect |
|---|---|
| Discoverable public article | Unwanted noindex or retrieval restrictions |
| Public page excluded from search | Targeted noindex and conditions allowing it to be read |
| Participant-only material | Authentication or another access-control mechanism |
| Separate test and production behavior | Environment-specific templates and delivery settings |
If changing robots.txt and page directives together, describe what each is meant to prevent. Check that a page whose noindex must be read is not simultaneously blocked from crawling.
Keep the complete URL in the review record. A correct observation from a test address does not establish the production state.
This purpose-first approach makes the settings easier to verify without using one search-oriented control as a substitute for a different kind of restriction.